大模型中图像如何被量化理解为文本

介绍

说到让图像被理解成文本,最容易想到的是目标识别:把每个类别的图片都训练一遍,模型就能认出来。但短板也很明显——训练集里没见过的类别,模型就不认识。这篇笔记介绍几种把图像和文本直接对应起来的模型。

CLIP

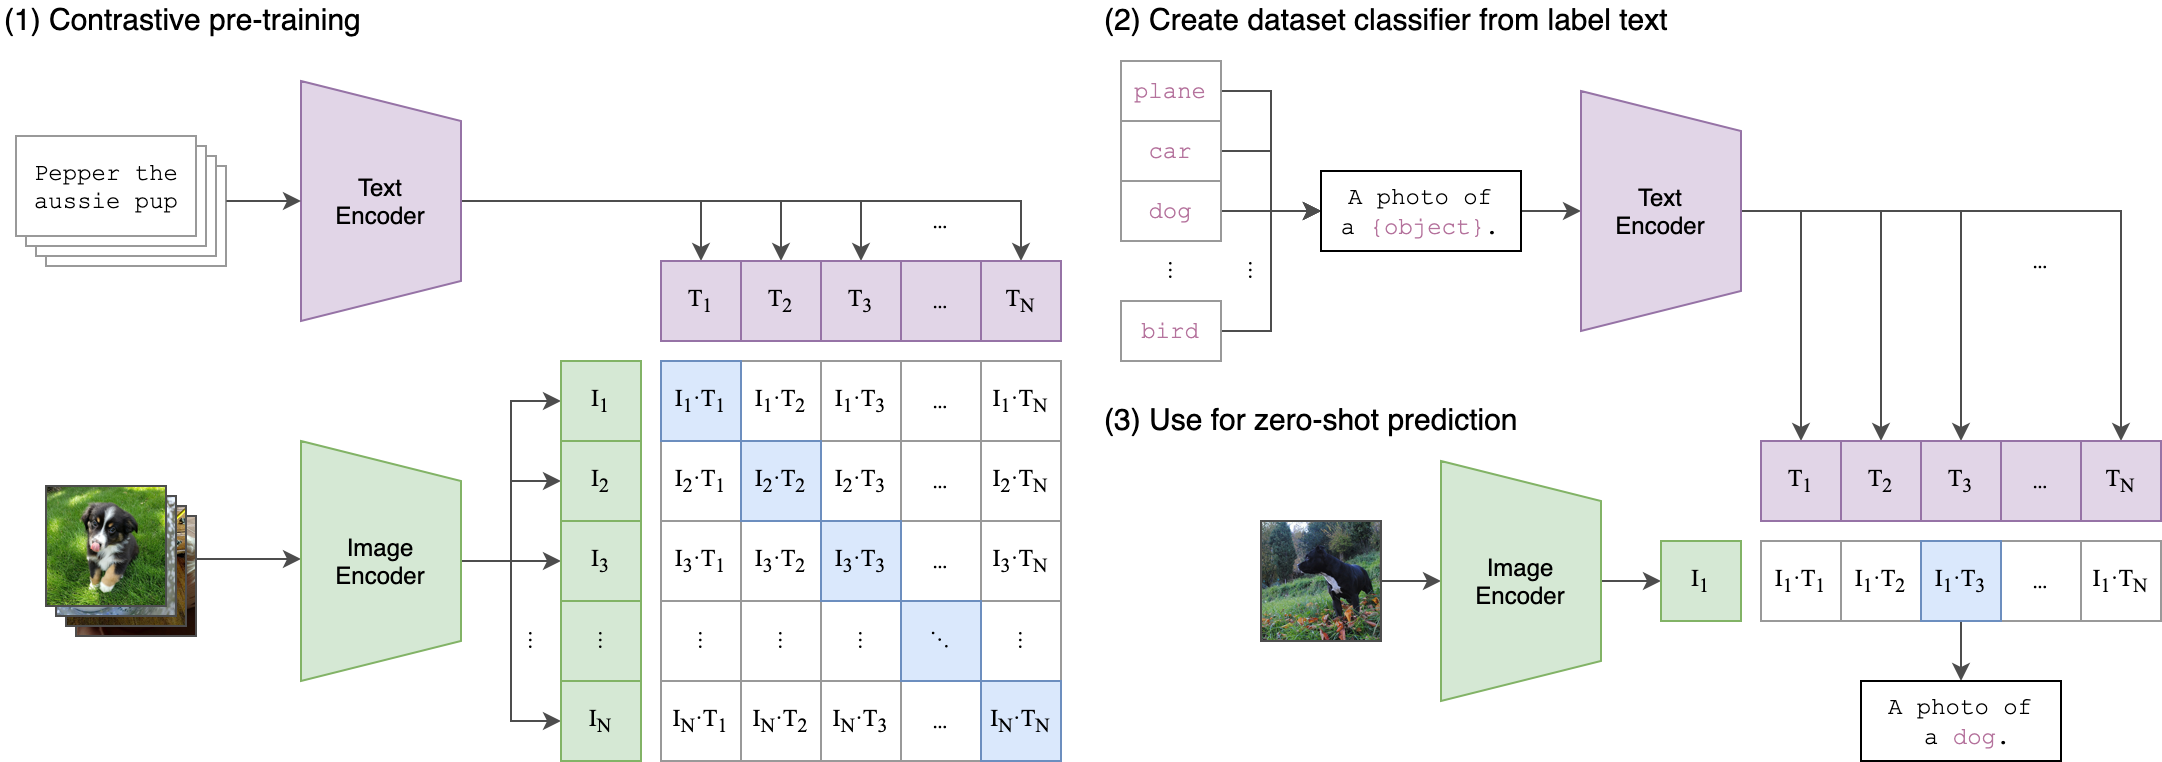
CLIP 做的事很直接:把图像和文本映射到同一个特征空间,再比较二者的相似度。

1

图里意思很直白:图片编码成一组向量,文本编码成一组向量,算两者的相似度。训练时把成对的文本和图像分别送进对应的编码器,得到两组维度相同的向量,用它们算损失,再更新编码器。

接下来要定的是两个编码器怎么选:文本这边一般用 Transformer(而不是 Seq2Seq),图像这边用 CNN 就够了——后面 ResNet 和 ViT 两种实现都会给。

论文里的性能对比就不贴了,直接看代码。

图像编码器(CNN)

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
class Bottleneck(nn.Module):
expansion = 4

def __init__(self, inplanes, planes, stride=1):
super().__init__()
#
self.conv1 = nn.Conv2d(inplanes, planes, 1, bias=False)
self.bn1 = nn.BatchNorm2d(planes)
self.relu1 = nn.ReLU(inplace=True)

self.conv2 = nn.Conv2d(planes, planes, 3, padding=1, bias=False)
self.bn2 = nn.BatchNorm2d(planes)
self.relu2 = nn.ReLU(inplace=True)

self.avgpool = nn.AvgPool2d(stride) if stride > 1 else nn.Identity()

self.conv3 = nn.Conv2d(planes, planes * self.expansion, 1, bias=False)
self.bn3 = nn.BatchNorm2d(planes * self.expansion)
self.relu3 = nn.ReLU(inplace=True)

self.downsample = None
self.stride = stride

if stride > 1 or inplanes != planes * Bottleneck.expansion:
# 确保步长为1
self.downsample = nn.Sequential(OrderedDict([
("-1", nn.AvgPool2d(stride)),
("0", nn.Conv2d(inplanes, planes * self.expansion, 1, stride=1, bias=False)),
("1", nn.BatchNorm2d(planes * self.expansion))
]))

def forward(self, x: torch.Tensor):
identity = x

out = self.relu1(self.bn1(self.conv1(x)))
out = self.relu2(self.bn2(self.conv2(out)))
out = self.avgpool(out)
out = self.bn3(self.conv3(out))

if self.downsample is not None:
identity = self.downsample(x)

out += identity
out = self.relu3(out)
return out

视觉Transformer

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
class VisionTransformer(nn.Module):
def __init__(self, input_resolution: int, patch_size: int, width: int, layers: int, heads: int, output_dim: int):
super().__init__()
self.input_resolution = input_resolution
self.output_dim = output_dim
self.conv1 = nn.Conv2d(in_channels=3, out_channels=width, kernel_size=patch_size, stride=patch_size, bias=False)

scale = width ** -0.5
self.class_embedding = nn.Parameter(scale * torch.randn(width))
self.positional_embedding = nn.Parameter(scale * torch.randn((input_resolution // patch_size) ** 2 + 1, width))
self.ln_pre = LayerNorm(width)

self.transformer = Transformer(width, layers, heads)

self.ln_post = LayerNorm(width)
self.proj = nn.Parameter(scale * torch.randn(width, output_dim))

def forward(self, x: torch.Tensor):
x = self.conv1(x) # shape = [*, width, grid, grid]
x = x.reshape(x.shape[0], x.shape[1], -1) # shape = [*, width, grid ** 2]
x = x.permute(0, 2, 1) # shape = [*, grid ** 2, width]
x = torch.cat(
[self.class_embedding.to(x.dtype) + torch.zeros(x.shape[0], 1, x.shape[-1], dtype=x.dtype, device=x.device),
x], dim=1) # shape = [*, grid ** 2 + 1, width]
x = x + self.positional_embedding.to(x.dtype)
x = self.ln_pre(x)

x = x.permute(1, 0, 2) # NLD -> LND
x = self.transformer(x)
x = x.permute(1, 0, 2) # LND -> NLD

x = self.ln_post(x[:, 0, :])

if self.proj is not None:
x = x @ self.proj

return x

最后把两者拼起来,就是完整的 CLIP:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
class CLIP(nn.Module):
def __init__(self,
embed_dim: int,
# vision
image_resolution: int,
vision_layers: Union[Tuple[int, int, int, int], int],
vision_width: int,
vision_patch_size: int,
# text
context_length: int,
vocab_size: int,
transformer_width: int,
transformer_heads: int,
transformer_layers: int
):
super().__init__()

self.context_length = context_length

if isinstance(vision_layers, (tuple, list)):
vision_heads = vision_width * 32 // 64
self.visual = ModifiedResNet(
layers=vision_layers,
output_dim=embed_dim,
heads=vision_heads,
input_resolution=image_resolution,
width=vision_width
)
else:
vision_heads = vision_width // 64
self.visual = VisionTransformer(
input_resolution=image_resolution,
patch_size=vision_patch_size,
width=vision_width,
layers=vision_layers,
heads=vision_heads,
output_dim=embed_dim
)

self.transformer = Transformer(
width=transformer_width,
layers=transformer_layers,
heads=transformer_heads,
attn_mask=self.build_attention_mask()
)

self.vocab_size = vocab_size
self.token_embedding = nn.Embedding(vocab_size, transformer_width)
self.positional_embedding = nn.Parameter(torch.empty(self.context_length, transformer_width))
self.ln_final = LayerNorm(transformer_width)

self.text_projection = nn.Parameter(torch.empty(transformer_width, embed_dim))
self.logit_scale = nn.Parameter(torch.ones([]) * np.log(1 / 0.07))

self.initialize_parameters()

def initialize_parameters(self):
nn.init.normal_(self.token_embedding.weight, std=0.02)
nn.init.normal_(self.positional_embedding, std=0.01)

if isinstance(self.visual, ModifiedResNet):
if self.visual.attnpool is not None:
std = self.visual.attnpool.c_proj.in_features ** -0.5
nn.init.normal_(self.visual.attnpool.q_proj.weight, std=std)
nn.init.normal_(self.visual.attnpool.k_proj.weight, std=std)
nn.init.normal_(self.visual.attnpool.v_proj.weight, std=std)
nn.init.normal_(self.visual.attnpool.c_proj.weight, std=std)

for resnet_block in [self.visual.layer1, self.visual.layer2, self.visual.layer3, self.visual.layer4]:
for name, param in resnet_block.named_parameters():
if name.endswith("bn3.weight"):
nn.init.zeros_(param)

proj_std = (self.transformer.width ** -0.5) * ((2 * self.transformer.layers) ** -0.5)
attn_std = self.transformer.width ** -0.5
fc_std = (2 * self.transformer.width) ** -0.5
for block in self.transformer.resblocks:
nn.init.normal_(block.attn.in_proj_weight, std=attn_std)
nn.init.normal_(block.attn.out_proj.weight, std=proj_std)
nn.init.normal_(block.mlp.c_fc.weight, std=fc_std)
nn.init.normal_(block.mlp.c_proj.weight, std=proj_std)

if self.text_projection is not None:
nn.init.normal_(self.text_projection, std=self.transformer.width ** -0.5)

def build_attention_mask(self):
# lazily create causal attention mask, with full attention between the vision tokens
# pytorch uses additive attention mask; fill with -inf
mask = torch.empty(self.context_length, self.context_length)
mask.fill_(float("-inf"))
mask.triu_(1) # zero out the lower diagonal
return mask

@property
def dtype(self):
return self.visual.conv1.weight.dtype

def encode_image(self, image):
return self.visual(image.type(self.dtype))

def encode_text(self, text):
x = self.token_embedding(text).type(self.dtype) # [batch_size, n_ctx, d_model]

x = x + self.positional_embedding.type(self.dtype)
x = x.permute(1, 0, 2) # NLD -> LND
x = self.transformer(x)
x = x.permute(1, 0, 2) # LND -> NLD
x = self.ln_final(x).type(self.dtype)

# x.shape = [batch_size, n_ctx, transformer.width]
# take features from the eot embedding (eot_token is the highest number in each sequence)
x = x[torch.arange(x.shape[0]), text.argmax(dim=-1)] @ self.text_projection

return x

def forward(self, image, text):
image_features = self.encode_image(image)
text_features = self.encode_text(text)

# normalized features
image_features = image_features / image_features.norm(dim=1, keepdim=True)
text_features = text_features / text_features.norm(dim=1, keepdim=True)

# cosine similarity as logits
logit_scale = self.logit_scale.exp()
logits_per_image = logit_scale * image_features @ text_features.t()
logits_per_text = logits_per_image.t()

# shape = [global_batch_size, global_batch_size]
return logits_per_image, logits_per_text

代码开源:https://github.com/openai/CLIP

VLP

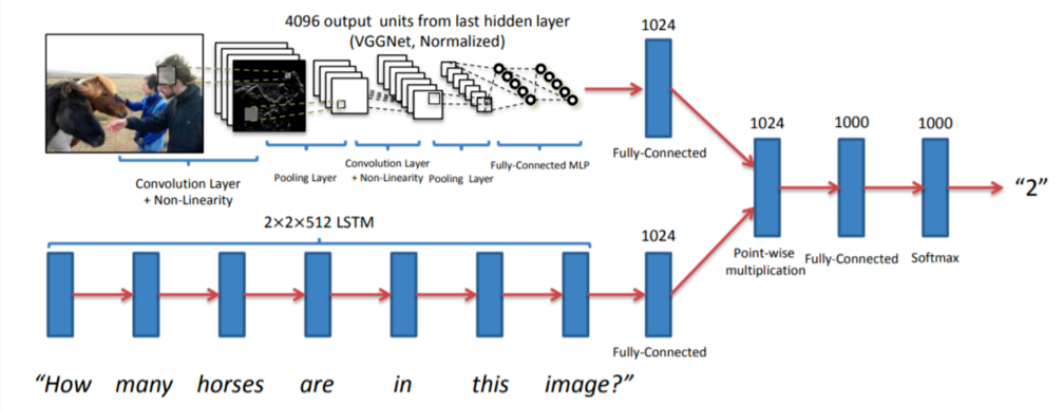
早期的 VLP 模型大多靠预训练的目标检测器提取图像特征,比 CLIP 出现得早,结构也更朴素。也有更简单的做法:文本编码器用 LSTM,图像编码器用 VGG,两边各输出一个 1024 维向量,点乘后过一层全连接,得到 Softmax 的输入。

4

ViLT

Transformer 在自然语言处理里是标配,放到计算机视觉里也照样能打。既然两边都在用 Transformer,能不能干脆用一个模型同时处理图像和文本?可以,这就是 ViLT(Vision-and-Language Transformer)。

下面是论文渲染(推荐使用Edge浏览器),Chrome浏览器会直接下载文件

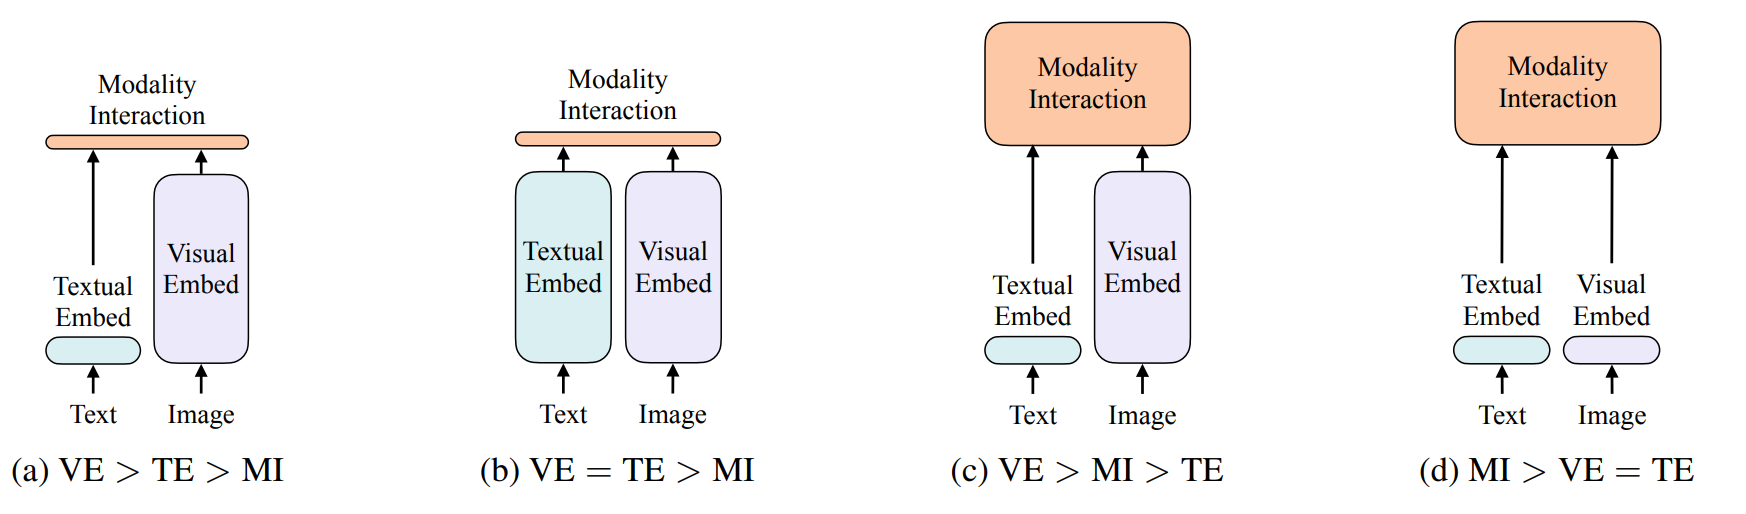
下图对比了几种 VLP 模型的计算量,矩形高度代表计算量;图中 VE 是视觉编码器,TE 是文本编码器,MI 是交互模块

1

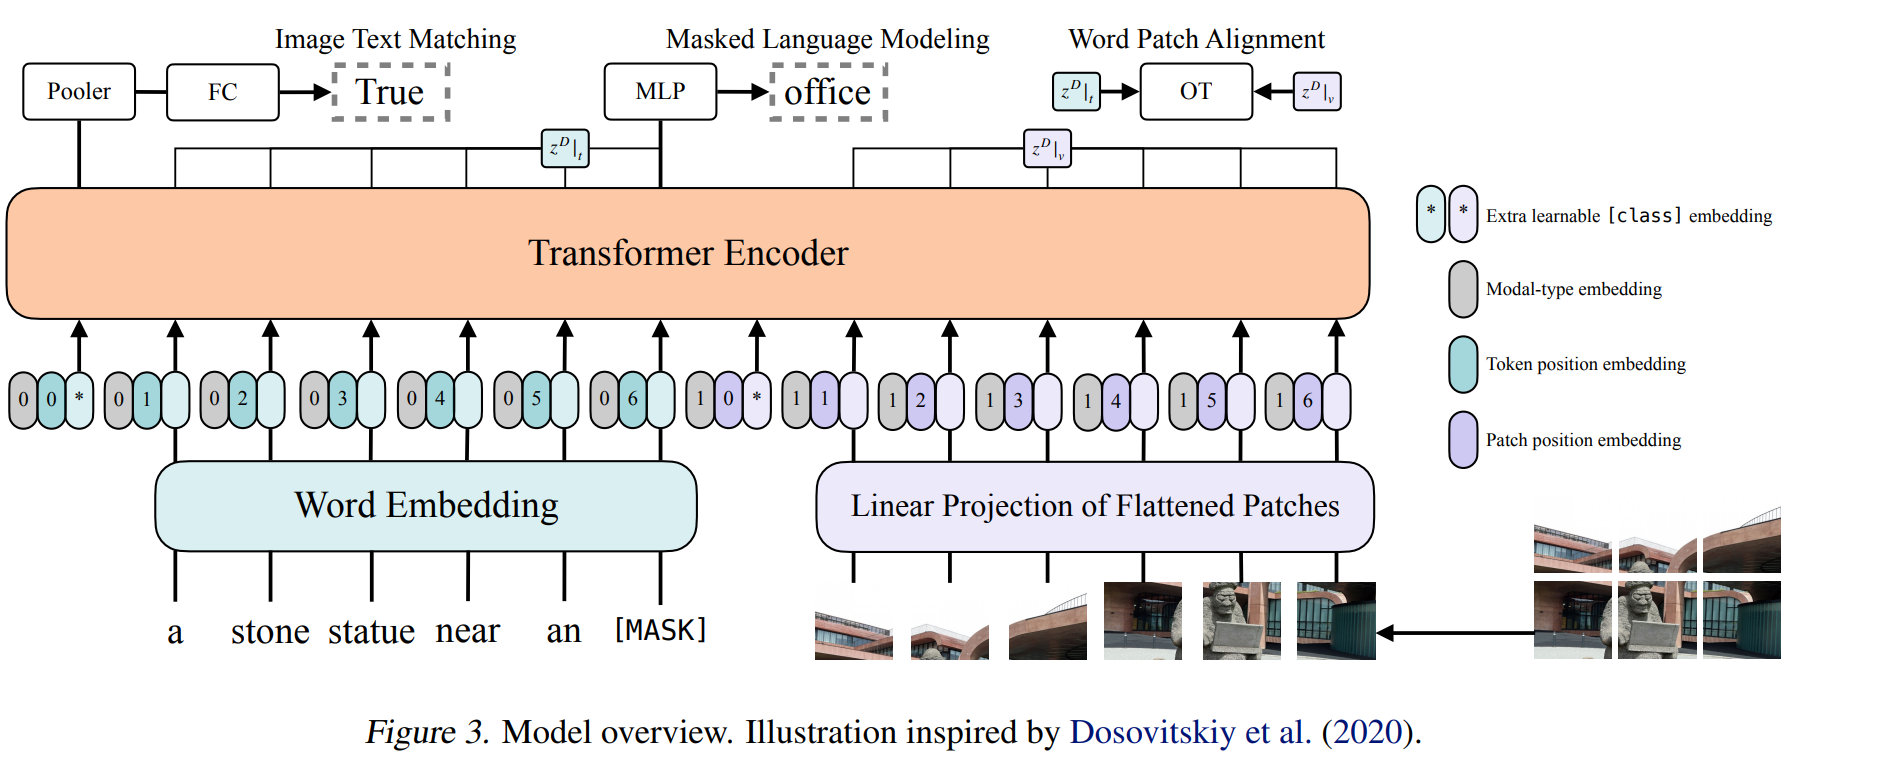
模型结构大致是这样:

3

ViLT 把 VLP 的流程简化了:不再需要目标检测器提区域特征,图像直接切 patch 过 ViT,文本 token 和图像 token 拼在一起送进同一个 Transformer。ViT 在往期博客里讲过,这里不重复,只需要知道图像编码器换成了 ViT。

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
141
142
143
144
145
146
147
148
149
150
151
152
153
154
155
156
157
158
159
160
161
162
163
164
165
166
167
168
169
170
171
172
173
174
175
176
177
178
179
180
181
182
183
184
185
186
187
188
189
190
191
192
193
194
195
196
197
198
199
200
201
202
203
204
205
206
207
208
209
210
211
212
213
214
215
216
217
218
219
220
221
222
223
224
225
226
227
228
229
230
231
232
233
234
235
236
237
238
239
240
241
242
243
244
245
246
247
248
249
250
251
252
253
254
255
256
257
258
259
260
261
262
263
264
265
266
267
268
269
270
271
272
273
274
275
276
277
# ViT 模型
class VisionTransformer(nn.Module):

def __init__(
self,
img_size=224,
patch_size=16,
in_chans=3,
num_classes=1000,
embed_dim=768,
depth=12,
num_heads=12,
mlp_ratio=4.0,
qkv_bias=True,
qk_scale=None,
representation_size=None,
drop_rate=0.0,
attn_drop_rate=0.0,
drop_path_rate=0.0,
norm_layer=None,
add_norm_before_transformer=False,
no_patch_embed_bias=False,
config=None,
):
"""
Args:
img_size (int, tuple): input image size
patch_size (int, tuple): patch size
in_chans (int): number of input channels
num_classes (int): number of classes for classification head
embed_dim (int): embedding dimension
depth (int): depth of transformer
num_heads (int): number of attention heads
mlp_ratio (int): ratio of mlp hidden dim to embedding dim
qkv_bias (bool): enable bias for qkv if True
qk_scale (float): override default qk scale of head_dim ** -0.5 if set
representation_size (Optional[int]): enable and set representation layer (pre-logits) to this value if set
drop_rate (float): dropout rate
attn_drop_rate (float): attention dropout rate
drop_path_rate (float): stochastic depth rate
hybrid_backbone (nn.Module): CNN backbone to use in-place of PatchEmbed module
norm_layer: (nn.Module): normalization layer
"""
super().__init__()
drop_rate = drop_rate if config is None else config["drop_rate"]

self.num_classes = num_classes
self.num_features = (
self.embed_dim
) = embed_dim # num_features for consistency with other models
norm_layer = norm_layer or partial(nn.LayerNorm, eps=1e-6)
self.add_norm_before_transformer = add_norm_before_transformer

self.patch_embed = PatchEmbed(
img_size=img_size,
patch_size=patch_size,
in_chans=in_chans,
embed_dim=embed_dim,
)
num_patches = self.patch_embed.num_patches

self.patch_size = patch_size
self.patch_dim = img_size // patch_size
self.cls_token = nn.Parameter(torch.zeros(1, 1, embed_dim))
self.pos_embed = nn.Parameter(torch.zeros(1, num_patches + 1, embed_dim))
self.pos_drop = nn.Dropout(p=drop_rate)

if add_norm_before_transformer:
self.pre_norm = norm_layer(embed_dim)

dpr = [
x.item() for x in torch.linspace(0, drop_path_rate, depth)
] # stochastic depth decay rule
self.blocks = nn.ModuleList(
[
Block(
dim=embed_dim,
num_heads=num_heads,
mlp_ratio=mlp_ratio,
qkv_bias=qkv_bias,
qk_scale=qk_scale,
drop=drop_rate,
attn_drop=attn_drop_rate,
drop_path=dpr[i],
norm_layer=norm_layer,
)
for i in range(depth)
]
)
self.norm = norm_layer(embed_dim)

trunc_normal_(self.pos_embed, std=0.02)
trunc_normal_(self.cls_token, std=0.02)
self.apply(self._init_weights)

def _init_weights(self, m):
if isinstance(m, nn.Linear):
trunc_normal_(m.weight, std=0.02)
if isinstance(m, nn.Linear) and m.bias is not None:
nn.init.constant_(m.bias, 0)
elif isinstance(m, nn.LayerNorm):
nn.init.constant_(m.bias, 0)
nn.init.constant_(m.weight, 1.0)

@torch.jit.ignore
def no_weight_decay(self):
return {"pos_embed", "cls_token"}

def mask_tokens(self, orig_image, feats):
"""
Prepare masked tokens inputs/labels for masked patch prediction: 80% MASK, 10% random, 10% original.
"""
img_unnorm = orig_image * 0.5 + 0.5
_, _, ph, pw = self.patch_embed.proj.weight.shape
with torch.no_grad():
img_unnorm_patch = F.conv2d(
img_unnorm,
weight=torch.ones(3, 1, ph, pw).to(img_unnorm) / (ph * pw),
bias=None,
stride=(ph, pw),
padding=0,
groups=3,
)
labels = (
((img_unnorm_patch * 255).long().flatten(start_dim=2, end_dim=3))
.permute(0, 2, 1)
.contiguous()
)

# We sample a few tokens in each sequence for MLM training (with probability `self.mlm_probability`)
probability_matrix = torch.full(labels.shape[:-1], 0.15)
masked_indices = torch.bernoulli(probability_matrix).bool()
labels[~masked_indices] = -100 # We only compute loss on masked tokens

# 80% of the time, we replace masked input tokens with tokenizer.mask_token ([MASK])
indices_replaced = (
torch.bernoulli(torch.full(labels.shape[:-1], 0.8)).bool() & masked_indices
)
feats[indices_replaced] = self.mask_token.to(feats)

return feats, labels

def visual_embed(self, _x, max_image_len=200, mask_it=False):
_, _, ph, pw = self.patch_embed.proj.weight.shape

x = self.patch_embed(_x)
x_mask = (_x.sum(dim=1) != 0).float()[:, None, :, :]
x_mask = F.interpolate(x_mask, size=(x.shape[2], x.shape[3])).long()
x_h = x_mask[:, 0].sum(dim=1)[:, 0]
x_w = x_mask[:, 0].sum(dim=2)[:, 0]

B, C, H, W = x.shape
spatial_pos = (
self.pos_embed[:, 1:, :]
.transpose(1, 2)
.view(1, C, self.patch_dim, self.patch_dim)
)
pos_embed = torch.cat(
[
F.pad(
F.interpolate(
spatial_pos, size=(h, w), mode="bilinear", align_corners=True,
),
(0, W - w, 0, H - h),
)
for h, w in zip(x_h, x_w)
],
dim=0,
)

pos_embed = pos_embed.flatten(2).transpose(1, 2)
x = x.flatten(2).transpose(1, 2)
patch_index = (
torch.stack(
torch.meshgrid(
torch.arange(x_mask.shape[-2]), torch.arange(x_mask.shape[-1])
),
dim=-1,
)[None, None, :, :, :]
.expand(x_mask.shape[0], x_mask.shape[1], -1, -1, -1)
.flatten(1, 3)
)
x_mask = x_mask.flatten(1)

if mask_it:
x, label = self.mask_tokens(_x, x)

if (
max_image_len < 0
or max_image_len is None
or not isinstance(max_image_len, int)
):
# suppose aug is 800 x 1333, then, maximum effective res is 800 x 1333 (if one side gets bigger, the other will be constrained and be shrinked)
# (800 // self.patch_size) * (1333 // self.patch_size) is the maximum number of patches that single image can get.
# if self.patch_size = 32, 25 * 41 = 1025
# if res is 384 x 640, 12 * 20 = 240
eff = x_h * x_w
max_image_len = eff.max()
else:
eff = x_h * x_w
max_image_len = min(eff.max(), max_image_len)

valid_idx = x_mask.nonzero(as_tuple=False)
non_valid_idx = (1 - x_mask).nonzero(as_tuple=False)
unique_rows = valid_idx[:, 0].unique()
valid_row_idx = [valid_idx[valid_idx[:, 0] == u] for u in unique_rows]
non_valid_row_idx = [
non_valid_idx[non_valid_idx[:, 0] == u] for u in unique_rows
]

valid_nums = [v.size(0) for v in valid_row_idx]
non_valid_nums = [v.size(0) for v in non_valid_row_idx]
pad_nums = [max_image_len - v for v in valid_nums]

select = list()
for i, (v, nv, p) in enumerate(zip(valid_nums, non_valid_nums, pad_nums)):
if p <= 0:
valid_choice = torch.multinomial(torch.ones(v).float(), max_image_len)
select.append(valid_row_idx[i][valid_choice])
else:
pad_choice = torch.multinomial(
torch.ones(nv).float(), p, replacement=True
)
select.append(
torch.cat(
[valid_row_idx[i], non_valid_row_idx[i][pad_choice]], dim=0,
)
)

select = torch.cat(select, dim=0)
x = x[select[:, 0], select[:, 1]].view(B, -1, C)
x_mask = x_mask[select[:, 0], select[:, 1]].view(B, -1)
patch_index = patch_index[select[:, 0], select[:, 1]].view(B, -1, 2)
pos_embed = pos_embed[select[:, 0], select[:, 1]].view(B, -1, C)

if mask_it:
label = label[select[:, 0], select[:, 1]].view(B, -1, 3)

label[x_mask == 0] = -100
label = torch.cat(
[torch.full((label.shape[0], 1, 3), -100).to(label), label,], dim=1,
)

cls_tokens = self.cls_token.expand(B, -1, -1)
x = torch.cat((cls_tokens, x), dim=1)
pos_embed = torch.cat(
(self.pos_embed[:, 0, :][:, None, :].expand(B, -1, -1), pos_embed), dim=1
)
x = x + pos_embed
x = self.pos_drop(x)

if self.add_norm_before_transformer:
x = self.pre_norm(x)

x_mask = torch.cat([torch.ones(x_mask.shape[0], 1).to(x_mask), x_mask], dim=1)

if mask_it:
return x, x_mask, (patch_index, (H, W)), label
else:
return x, x_mask, (patch_index, (H, W)), None

def forward_features(self, _x, max_image_len=144, mask_it=False):
x, x_mask, patch_index, label = self.visual_embed(
_x, max_image_len=max_image_len, mask_it=mask_it
)

for blk in self.blocks:
x, _ = blk(x, mask=x_mask)

x = self.norm(x)
return x, x_mask, label

def forward(self, x, max_image_len=-1):
x, _, _ = self.forward_features(x, max_image_len=max_image_len)
x = x[:, 0]
x = self.head(x)
return x

既然用了 Transformer,注意力就是核心。ViLT 在预训练阶段用了 MPP(Masked Patch Prediction,掩码图像块预测)这个目标,整体结构本质上还是 BERT 那一套。

总结

以上就是几种把图像和文本对应起来的模型,也能看到 Transformer 在视觉领域是怎么用的。


大模型中图像如何被量化理解为文本
https://blog.minloha.cn/posts/1608431f43a3f12024020843.html
作者
Minloha
发布于
2024年2月8日
更新于
2024年2月8日
许可协议