关于TCN:时空卷积网络的妙用

介绍

TCN是时域卷积网络(Temporal Convolutional Network)的简称,它由具有相同输入和输出长度的扩张的、因果的1D卷积层组成,是一种新型的序列模型。论文地址:https://arxiv.org/abs/1803.01271

模型

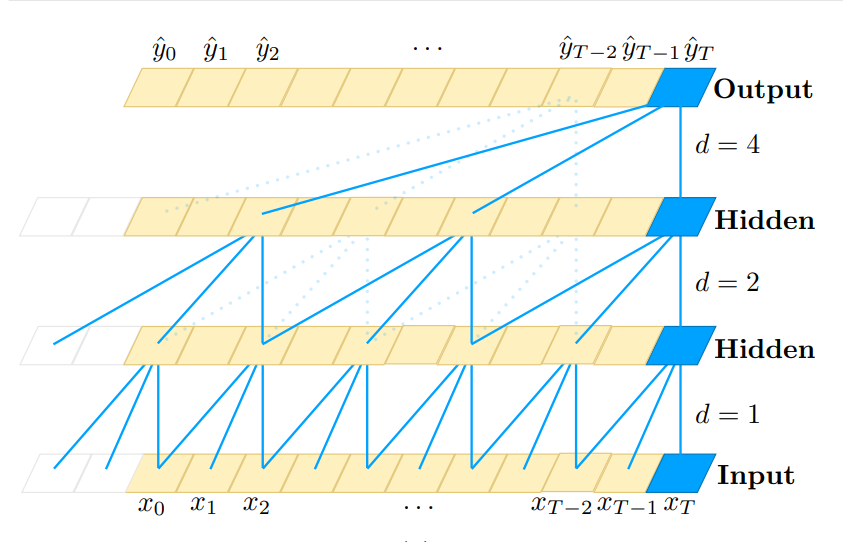
在传统的CNN中,我们使用到的是矩阵进行的二维卷积,每一层卷积后的输出都会让尺寸变小,对于序列而言,我们一样可以进行卷积,因为是在一维空间内,也叫一维卷积。我们可以用一个向量当作滑动窗口进行卷积。为了弥补数据的缺失,就有了padding的过程,一维的padding可以选择在左侧补0或者在右侧补0,一般选择左侧填充。结合两者,我们得到的就是因果卷积。

在二维卷积里面,我们了解过膨胀卷积,一维里也有,也就是空洞卷积。

1

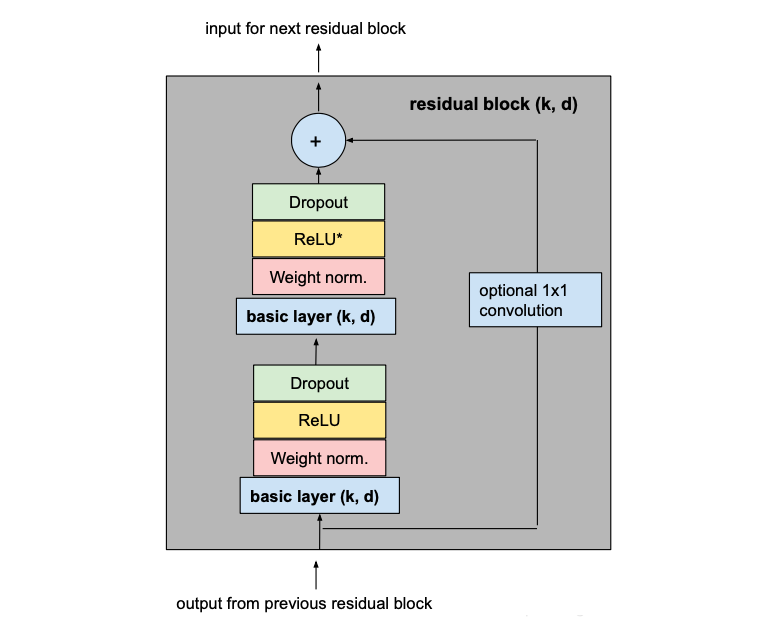
TCN的模型结构如下,数据需要经过两次一维卷积后求和,保证数据的连贯。

1

相关代码如下:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
from torch.nn.utils.parametrizations import weight_norm

# 裁剪模块,负责裁掉膨胀卷积右侧多出来的padding
class Chomp1d(nn.Module):
def __init__(self, chomp_size):
super(Chomp1d, self).__init__()
self.chomp_size = chomp_size

def forward(self, x):
return x[:, :, :-self.chomp_size].contiguous()

# 时间卷积模块
class TemporalBlock(nn.Module):
def __init__(self, n_inputs, n_outputs, kernel_size, stride, dilation, padding, dropout=0.2):
super(TemporalBlock, self).__init__()
self.conv1 = nn.Conv1d(n_inputs, n_outputs, kernel_size,
stride=stride, padding=padding, dilation=dilation)
self.chomp1 = Chomp1d(padding)
self.relu1 = nn.ReLU()
self.dropout1 = nn.Dropout(dropout)

self.conv2 = nn.Conv1d(n_outputs, n_outputs, kernel_size,
stride=stride, padding=padding, dilation=dilation)
self.chomp2 = Chomp1d(padding)
self.relu2 = nn.ReLU()
self.dropout2 = nn.Dropout(dropout)

self.net = nn.Sequential(self.conv1, self.chomp1, self.relu1, self.dropout1,
self.conv2, self.chomp2, self.relu2, self.dropout2)
self.downsample = nn.Conv1d(n_inputs, n_outputs, 1) if n_inputs != n_outputs else None
self.relu = nn.ReLU()
self.init_weights()
# 先初始化再套weight_norm,否则初始化不生效
weight_norm(self.conv1)
weight_norm(self.conv2)

# 高斯初始化
def init_weights(self):
self.conv1.weight.data.normal_(0, 0.01)
self.conv2.weight.data.normal_(0, 0.01)
if self.downsample is not None:
self.downsample.weight.data.normal_(0, 0.01)

# 前传
def forward(self, x):
out = self.net(x)
res = x if self.downsample is None else self.downsample(x)
return self.relu(out + res)

我们把Block封装成Model,最后做成nn.Module:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
# 基础网络
class TemporalConvNet(nn.Module):
def __init__(self, num_inputs, num_channels, kernel_size=2, dropout=0.2):
super(TemporalConvNet, self).__init__()
layers = []
num_levels = len(num_channels)
for i in range(num_levels):
dilation_size = 2 ** i
in_channels = num_inputs if i == 0 else num_channels[i - 1]
out_channels = num_channels[i]
layers += [TemporalBlock(in_channels, out_channels, kernel_size, stride=1, dilation=dilation_size,
padding=(kernel_size - 1) * dilation_size, dropout=dropout)]
self.network = nn.Sequential(*layers)

def forward(self, x):
return self.network(x.float())


'''
@author: Minloha
@:parameter: input_size: 输入维度
num_channels: 每一层的输出维度
kernel_size: 卷积核大小
dropout: dropout比例
@:return: y: 输出
'''
class TCN(nn.Module):
def __init__(self, input_size, num_channels,
kernel_size=2, dropout=0.3):
super(TCN, self).__init__()
self.tcn = TemporalConvNet(input_size, num_channels, kernel_size=kernel_size, dropout=dropout)

def forward(self, input):
return self.tcn(input)

最后我们把训练和评估写一下:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
def train_ch8(net, train_iter, test_iter, loss, trainer, num_epochs, device):
print('training on', device)
net.to(device)
for epoch in range(num_epochs):
train_loss_sum, n, start = 0.0, 0, time.time()
for x, y in train_iter:
x = x.to(device)
y = y.to(device)
y_hat = net(x)
l = loss(y_hat, y)
trainer.zero_grad()
l.backward()
trainer.step()
train_loss_sum += l.cpu().item() * y.shape[0]
n += y.shape[0]
test_acc = evaluate_accuracy(test_iter, net)
print('epoch %d, loss %.4f, test acc %.3f, time %.1f sec'
% (epoch + 1, train_loss_sum / n, test_acc, time.time() - start))

def evaluate_accuracy(data_iter, net, device=None):
if device is None and isinstance(net, torch.nn.Module):
device = list(net.parameters())[0].device
acc_sum, n = 0.0, 0
with torch.no_grad():
for x, y in data_iter:
x = x.to(device)
y = y.to(device)
acc_sum += (net(x).argmax(dim=1) == y).float().sum().cpu().item()
n += y.numel()
return acc_sum / n if n > 0 else 0

接下来就可以进行训练了,这里训练用的是github上给出的数据集。

1
2
3
4
5
6
7
8
9
10
11
12
13
14
def main():
net = nn.Sequential(
TCN(4, [4], kernel_size=4, dropout=0),
)
device = torch.device('cuda:0' if torch.cuda.is_available() else 'cpu')
loss = nn.CrossEntropyLoss()
trainer = torch.optim.SGD(net.parameters(), lr=0.1)
train_data_O = SequenceDataset(train_x, train_y)
test_data_O = SequenceDataset(test_x, test_y)
train_iter = torch.utils.data.DataLoader(train_data_O, batch_size=4, shuffle=True)
test_iter = torch.utils.data.DataLoader(test_data_O, batch_size=30, shuffle=False)
train_ch8(net, train_iter, test_iter, loss, trainer, 120, device)

pass

训练

下面是当时跑出来的输出(只截取了最后一部分):

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
epoch 91, loss 0.3645, test acc 0.870, time 0.0 sec
epoch 92, loss 0.3685, test acc 0.875, time 0.0 sec
epoch 93, loss 0.3681, test acc 0.872, time 0.0 sec
epoch 94, loss 0.3596, test acc 0.877, time 0.0 sec
epoch 95, loss 0.3653, test acc 0.875, time 0.0 sec
epoch 96, loss 0.3582, test acc 0.867, time 0.0 sec
epoch 97, loss 0.3604, test acc 0.870, time 0.0 sec
epoch 98, loss 0.3709, test acc 0.886, time 0.0 sec
epoch 99, loss 0.3612, test acc 0.880, time 0.0 sec
epoch 100, loss 0.3622, test acc 0.877, time 0.0 sec
epoch 101, loss 0.3552, test acc 0.875, time 0.0 sec
epoch 102, loss 0.3529, test acc 0.881, time 0.0 sec
epoch 103, loss 0.3605, test acc 0.864, time 0.0 sec
epoch 104, loss 0.3625, test acc 0.877, time 0.0 sec
epoch 105, loss 0.3634, test acc 0.883, time 0.0 sec
epoch 106, loss 0.3551, test acc 0.869, time 0.0 sec
epoch 107, loss 0.3546, test acc 0.889, time 0.0 sec
epoch 108, loss 0.3546, test acc 0.873, time 0.0 sec
epoch 109, loss 0.3594, test acc 0.881, time 0.0 sec
epoch 110, loss 0.3537, test acc 0.867, time 0.0 sec
epoch 111, loss 0.3527, test acc 0.884, time 0.0 sec
epoch 112, loss 0.3510, test acc 0.889, time 0.0 sec
epoch 113, loss 0.3479, test acc 0.883, time 0.0 sec
epoch 114, loss 0.3472, test acc 0.875, time 0.0 sec
epoch 115, loss 0.3503, test acc 0.883, time 0.0 sec
epoch 116, loss 0.3503, test acc 0.880, time 0.0 sec
epoch 117, loss 0.3494, test acc 0.881, time 0.0 sec
epoch 118, loss 0.3450, test acc 0.873, time 0.0 sec
epoch 119, loss 0.3464, test acc 0.875, time 0.0 sec
epoch 120, loss 0.3482, test acc 0.878, time 0.0 sec

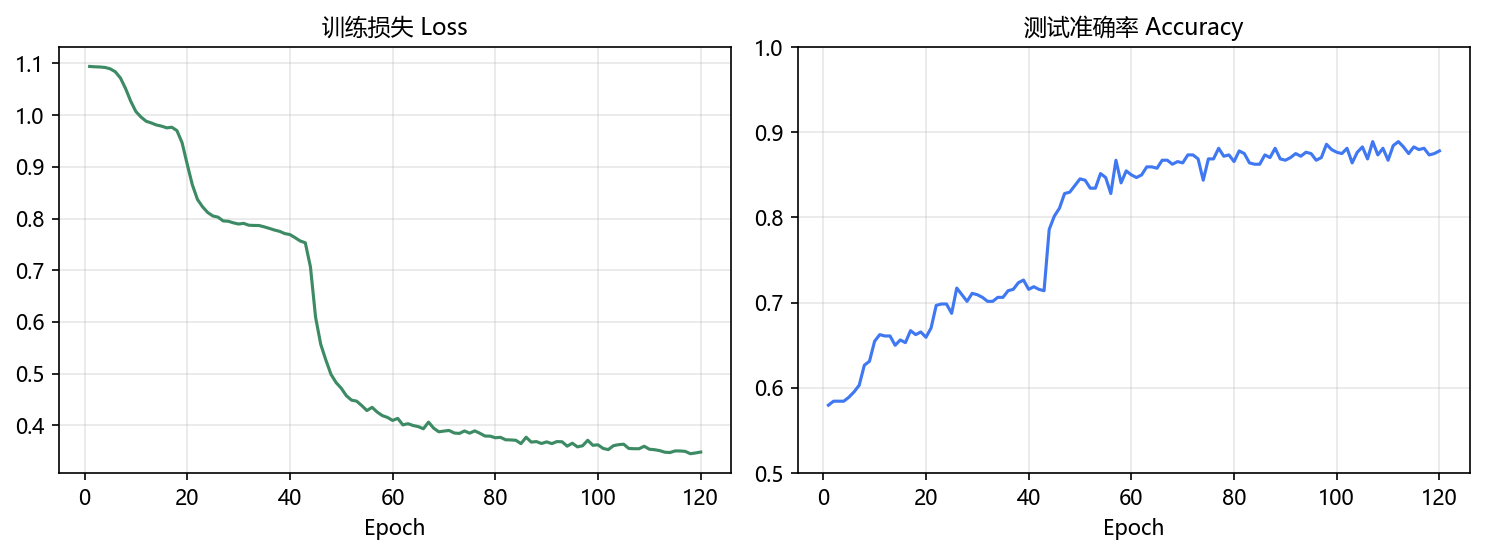
每轮的 loss 和准确率画成曲线更直观:

训练曲线

总结

TCN的关键就两块:膨胀加因果卷积保证不偷看未来,残差结构让深层网络能训得动。论文里那个看着吓人的感受野公式,其实就是膨胀系数一层层乘加撑出来的。代码在上面都能直接跑,感兴趣的可以换自己的序列数据试试。


关于TCN:时空卷积网络的妙用
https://blog.minloha.cn/posts/003018baf8b03a2023063001.html
作者
Minloha
发布于
2023年6月30日
更新于
2023年6月30日
许可协议